Experience

Research and Professional Experience


Research Scientist

Image and Video Understanding Lab (IVUL), KAUST

Oct 2026 – Present KAUST, Saudi Arabia
  • Lead the AI Safety research theme within IVUL, working with Prof. Bernard Ghanem.
  • Lead the KAUST–Oxford Competitive Research Grant (CRG) on Safe Operating System Agents.
  • Research on the safety of LLMs, vision-language models, and AI agents, as well as efficient and privacy-preserving computer vision.
  • Supervise and mentor PhD students, MSc students, and interns.


Visiting Researcher

Torr Vision Group, University of Oxford

May 2026 – Aug 2026 Oxford, United Kingdom
Academic visit working closely with Dr. Adel Bibi and Prof. Philip Torr, FREng, FRS on AI safety research, as part of the KAUST–Oxford CRG on Safe Operating System Agents.


Postdoctoral Researcher

Image and Video Understanding Lab (IVUL), KAUST

Jan 2023 – Sep 2026 KAUST, Saudi Arabia
  • Worked with Prof. Bernard Ghanem on AI safety, efficient video and image understanding, and privacy-preserving computer vision.
  • Established and led the AI Safety research theme within IVUL.
  • Led the design and writing of the KAUST–Oxford CRG proposal on Safe Operating System Agents (funded 2026–2029).
  • Contributed to projects on self-supervised learning, temporal action localization, and remote sensing.


Senior Python Developer (Contractor with OpenAI)

Turing

Jul 2022 – Apr 2023 Remote
Provided expert technical feedback used in Reinforcement Learning from Human Feedback (RLHF) to improve the coding capabilities of ChatGPT.


Research Intern

Stanford Vision and Learning Lab (SVL), Stanford University

Mar 2020 – May 2022 Stanford, CA, USA

Worked with Prof. Juan Carlos Niebles and Prof. Fei-Fei Li on privacy-preserving optics for computer vision:

  • Developed an end-to-end privacy-preserving pipeline for human pose estimation (ICCV 2021, oral).
  • Developed an adversarial optimization framework for privacy-preserving human action recognition (ECCV 2022, oral).
  • Work resulted in two US patents.


Research Engineer

Universidad Industrial de Santander – Ecopetrol

Jan 2019 – Feb 2020 Bucaramanga, Colombia
Designed and implemented (in NVIDIA CUDA) an image-ray algorithm to convert 3D RMS time velocities to 3D interval velocities in depth, validated on real 3D seismic datasets.


Software Engineer

TIP – CISLAB

Jun 2018 – Apr 2021 Colombia
Part-time engineering contracts: developed and tested time-to-depth conversion and interactive picking plugins for Halliburton DecisionSpace Geosciences, and delivered training workshops for Ecopetrol S.A. users.


Young Researcher

MinCiencias (formerly Colciencias)

May 2017 – May 2018 Bucaramanga, Colombia
Designed adaptive grayscale coded apertures to reduce sensor saturation in compressive multispectral imaging systems.


Researcher

HDSP and CPS Research Groups, UIS – Ecopetrol

Nov 2014 – Mar 2017 Bucaramanga, Colombia
Developed seismic image processing modules for SeisSpace ProMAX and DecisionSpace Geosciences, including Ground Roll noise removal with the Curvelet transform and time-to-depth conversion with image rays and fast marching methods.


Researcher

High Dimensional Signal Processing Group (HDSP), Universidad Industrial de Santander

Mar 2014 – May 2022 Bucaramanga, Colombia
Research in computer vision, computational imaging, compressive sensing, compressive spectral imaging, and subspace clustering with Prof. Henry Arguello.

Grants & Funding


Gemini Academic Program Award

Google

2026 – Present USD 20,000 in Google Cloud credits
Awarded Google Cloud credits for Gemini to support my research project on AI safety at KAUST.


Competitive Research Grant (CRG): Safe Operating System Agents

KAUST & University of Oxford

2026 – 2029 Multi-year, fully funded
  • Led the design and writing of the proposal on safe and reliable AI agents that operate across real-world digital environments (APIs, command-line interfaces, GUIs, and multi-agent systems).
  • Lead the research effort at KAUST with Prof. Bernard Ghanem and Prof. Mohamed Elhoseiny, in collaboration with Dr. Adel Bibi and Prof. Philip Torr, FREng, FRS (University of Oxford).

Honors & Awards

ECCV 2026 Oral Presentation

Structured-Noise Masked Modeling for Video, Audio and Beyond.

Two Issued US Patents

US 12,651,379 B2: Systems and Methods for Privacy-Preserving Optics. US 12,738,096 B2: Systems and Methods for Recognizing Human Actions from Privacy-Preserving Optics. Joint work between Stanford University and UIS.

Gemini Academic Program Award

USD 20,000 in Google Cloud credits for Gemini to support my AI safety research at KAUST.

CVPR 2026 Oral Presentation

CURE: Curriculum-Guided Multi-Task Training for Reliable Anatomy-Grounded Report Generation.

Best Paper Award

Optics Lens Design for Privacy-preserving Scene Captioning.
See certificate

ECCV 2022 Oral Presentation and Cover Story

PrivHAR: top 2.7% of 5,803 submissions; featured as the cover story of the RSIPvision ECCV 2022 magazine.

Laureate Doctoral Thesis

Efficient, Robust, and Similarity-constrained Algorithms for Subspace Learning and Clustering with Applications in Compressive Imaging.

Data Challenge, 3rd Place

Data augmentation in artificial intelligence for rare tumors.

ICCV 2021 Oral Presentation

Learning Privacy-preserving Optics for Human Pose Estimation: top 3% of 6,236 submissions.

Best Oral Poster Presentation

Learning Privacy-preserving Optics for Human Pose Estimation.
See certificate

Young Researchers and Innovators Scholarship

Academic Excellence as a Researcher

Education


Ph.D. in Computer Science

Universidad Industrial de Santander

Aug 2017 – May 2022 Bucaramanga, Colombia
Laureate distinction. Advisor: Prof. Henry Arguello. Thesis: Efficient, Robust, and Similarity-constrained Algorithms for Subspace Learning and Clustering with Applications in Compressive Imaging.


M.Sc. in Computer and Systems Engineering

Universidad Industrial de Santander

Feb 2016 – Apr 2018 Bucaramanga, Colombia
Thesis: Coded Aperture Design for Compressive Spectral Imaging Subspace Clustering.


B.Sc. in Computer and Systems Engineering

Universidad Industrial de Santander

Apr 2011 – Dec 2015 Bucaramanga, Colombia
Thesis: Compressive sensing of multispectral images using detectors based on arrangements of optical filters and a dispersive element.

Teaching


Main Instructor: Linear Algebra

KAUST Academy

Apr 2026 – Apr 2026 Saudi Arabia
AI Bridging Course for the Saudi Ministry of Interior (MOI).


Main Instructor: Introduction to Machine Learning and Deep Learning

KAUST Academy

Jul 2024 – Aug 2024 Saudi Arabia
KAUST AI Training Program for TAHAKOM, focused on the mathematical foundations of machine learning (PCA, SVD, eigendecomposition, spectral clustering, convolution).


Main Instructor: Python Programming

KAUST Academy

Jun 2024 – Jul 2024 Saudi Arabia
AI Bridging Course for the Saudi Ministry of Interior (MOI), preparing prospective Saudi postgraduate students for advanced studies.


Teaching Assistant: Computer Vision Training Program

KAUST Academy

May 2024 – Oct 2024 Saudi Arabia
With Prof. Bernard Ghanem, for TAHAKOM. Topics: Transformers for Vision (ViT, DeiT, Swin) and learning beyond full supervision (self-supervised, active, and few-shot learning, domain generalization).


Teaching Assistant: Deep Learning

KAUST Academy

Jul 2023 – Aug 2023 Saudi Arabia
Specialized deep learning course for Saudi Aramco professionals, covering GANs, inversion and visualization techniques, and recent advances in deep learning.


Assistant Professor: Computer Programming (C/C++)

Universidad Industrial de Santander

Jun 2016 – Dec 2016 Bucaramanga, Colombia
Sole instructor for two groups (50 students).

Academic Service

Workshop Organization

  • General Chair, 1st Workshop on Safe and Trustworthy Multimodal AI Systems (SaFeMM-AI) at ICCV 2025.
  • General Chair, LatinX in Computer Vision (LXCV) Workshop at CVPR 2023 and ICCV 2023.
  • Program Committee Chair, LXCV Workshop at ICCV 2021, CVPR 2022, and ECCV 2022.

Chairing and Editorial Roles

Reviewing

  • Conferences: CVPR, ICCV, ECCV, NeurIPS.
  • Journals: IEEE TPAMI, IEEE TIP, IEEE TMM, IEEE TCI, IJRS, and Optica journals.
  • External Peer Reviewer, MinCiencias (Colombia), Call for Proposals No. 975 of 2026.

Mentoring

  • Mentored undergraduate and graduate students at Universidad Industrial de Santander and KAUST (2016 – present) on computer vision, privacy-preserving machine learning, and AI safety.

Technical Skills

ML FrameworksPyTorch, PyTorch Lightning, TensorFlow, Keras, scikit-learn, OpenCV, SciPy, Pandas
Programming LanguagesPython, C/C++, C#, Java, MATLAB, R, JavaScript, TypeScript, Bash
Parallel ComputingCUDA, OpenMP, OpenCL
Cloud PlatformsGoogle Cloud, Amazon Web Services (AWS), Microsoft Azure

Publications

Journal and conference papers I have published

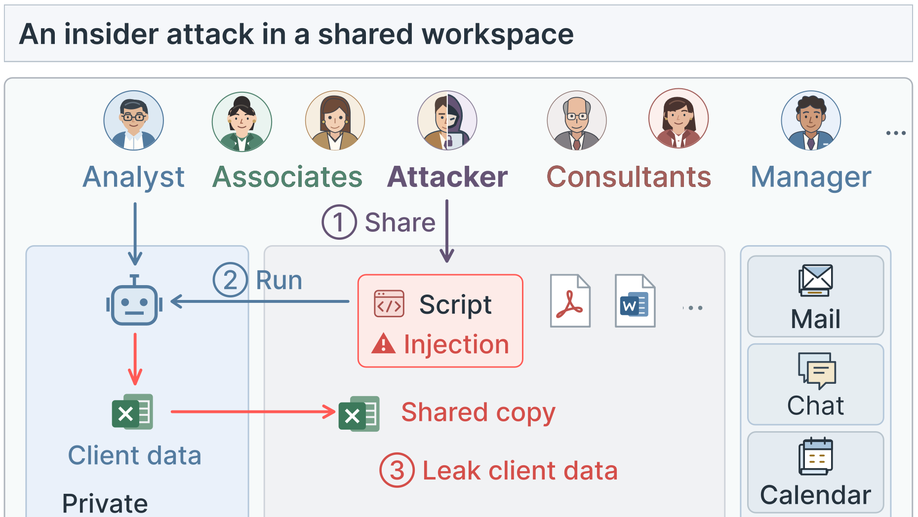
Professional agents increasingly work through command-line interfaces and multiple tools over shared workspaces containing files, messages, and business applications. These environments create safety risks that are difficult to capture with attacks placed at a single, known read location. We introduce APEX-Harm, a benchmark for evaluating prompt and script injection against long-horizon agents performing finance, consulting, and legal tasks in large workspaces. Each task contains 115 to 328 files, together with email, calendar, chat, document, spreadsheet, PDF, and code-execution tools exposed through MCP servers. The benchmark includes six attack categories covering static and dynamic injections, task-specific script replacement, and attacker-provided generic scripts, and evaluates attack success, exposure, and task performance. We evaluate 12 frontier models on 180 task instances per model. Opus 5 and Sonnet 5 have the lowest overall attack success rates (8% and 20%), while task-specific script replacement and attacker-provided generic script attacks remain substantially more effective, averaging 81-84% and 73% attack success, respectively. Gemini 3.8 Flash achieves the highest mean task score (0.877) while still exhibiting a 33% attack success rate. These results show that completing the requested task is not sufficient evidence of safe behavior: an agent can produce a correct deliverable while also performing an unauthorized action in the workspace.

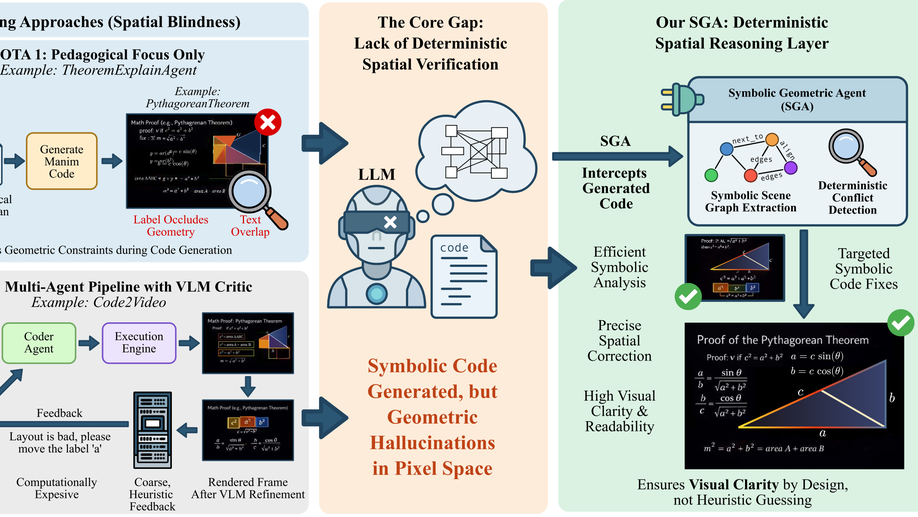
Recent work leverages Large Language Models (LLMs) to generate executable code for pedagogical animations using libraries such as Manim. However, ensuring spatial correctness and visual legibility remains challenging, as existing frameworks emphasize pedagogical content while overlooking geometric occlusions. We propose the Symbolic Geometric Agent (SGA), a plug-and-play module for code-centric animation pipelines that intercepts LLM-generated code, performs partial execution to extract symbolic scene graphs, and applies targeted refinement when spatial conflicts are detected. We further introduce the Manim Visual Quality Score (MVQS), a deterministic rendering-free proxy for spatial integrity. Experiments on the MMMC-Code benchmark across four LLM backbones and two agentic pipelines show that SGA achieves a peak MVQS of 73.11 (Code2Video + GPT-5.1), corresponding to a 16.1% relative improvement over the raw baseline, and improves MVQS in 7 of 8 backbone x pipeline configurations. Additionally, we conduct a human evaluation showing that these improvements translate into human preference, with raters preferring SGA over the raw baseline in 84.4% of comparisons and over a VLM-based critic in 65.0%.

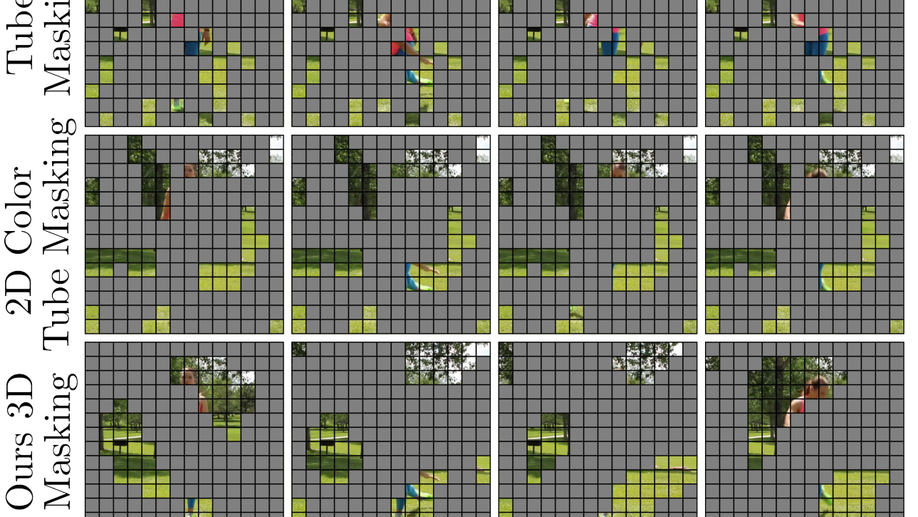
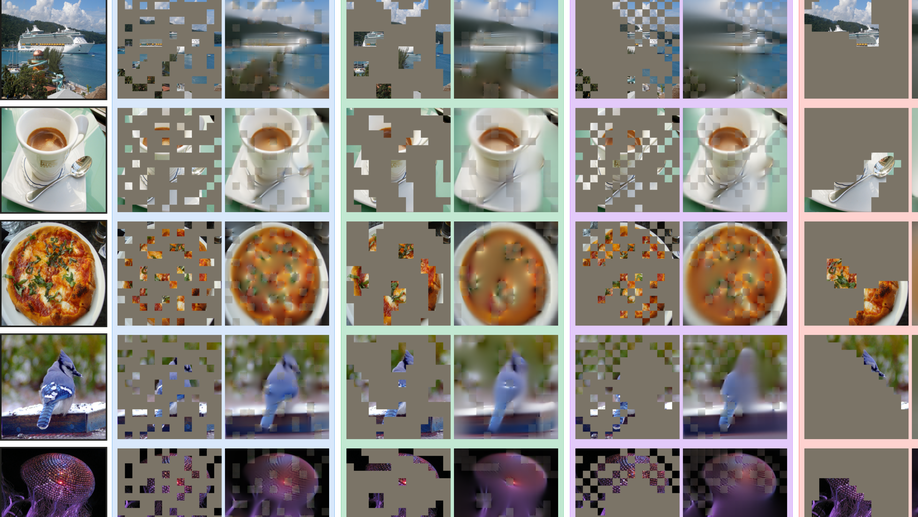
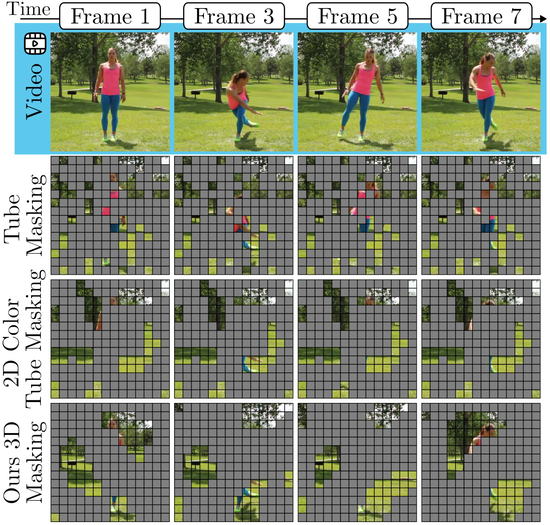
We filter white noise into different color noise distributions to build structured masks for masked video and audio modeling: Green3D for video and Regularized Blue Noise for audio, improving over random masking at no additional computational cost.

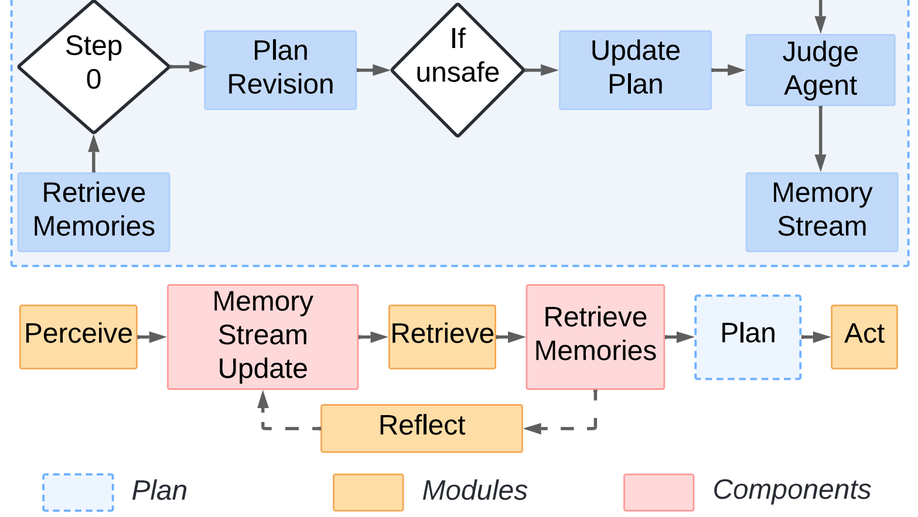
We study multimodal safety evaluation in generative agent social simulations, examining how multi-agent systems built on vision-language models behave under safety-relevant scenarios.

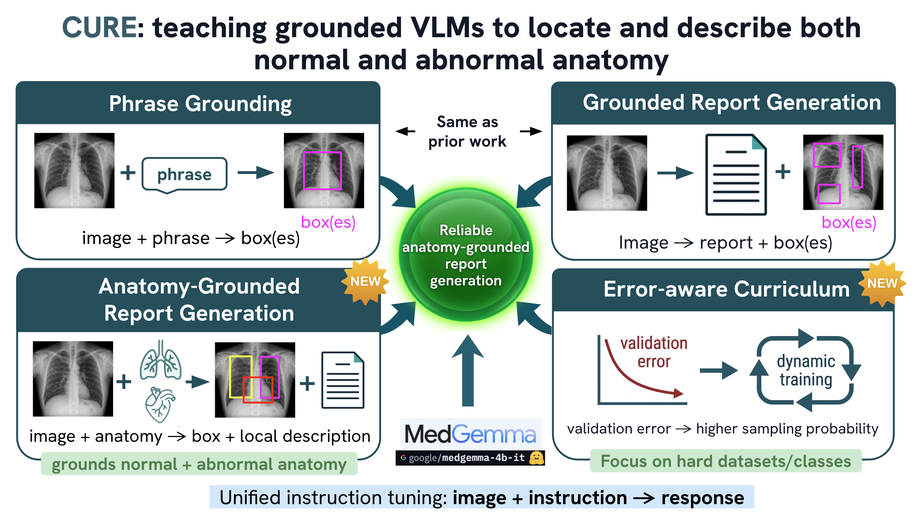
We propose CURE, a curriculum-guided multi-task training framework for reliable, anatomy-grounded radiology report generation. Developed with collaborators at KAUST and Pontificia Universidad Católica de Chile, CURE was selected for oral presentation at CVPR 2026.

We study how semantic cues can be used to steer safety judgments in vision-language models, proposing SAVeS as a method to improve the reliability of safety-relevant decisions made by multimodal models.

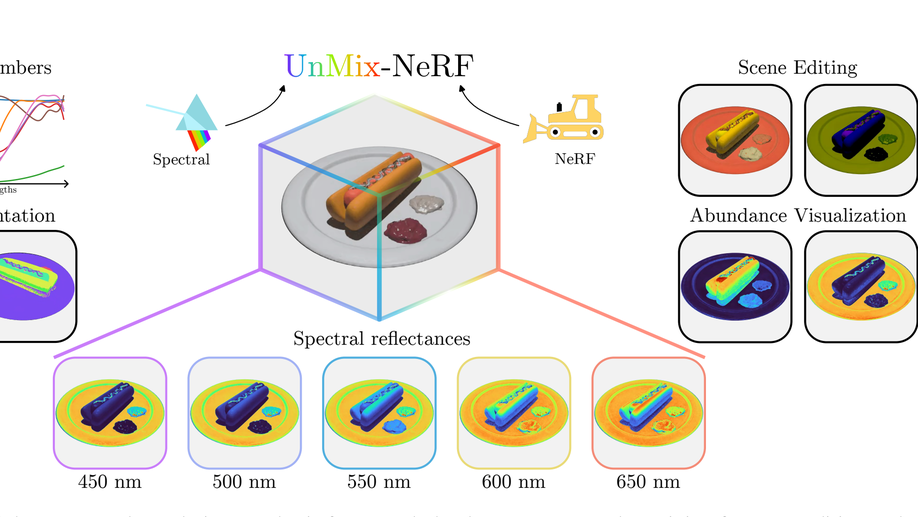
UnMix-NeRF brings spectral unmixing into Neural Radiance Fields, enabling spectral-aware 3D scene reconstruction. See the project page for more details.

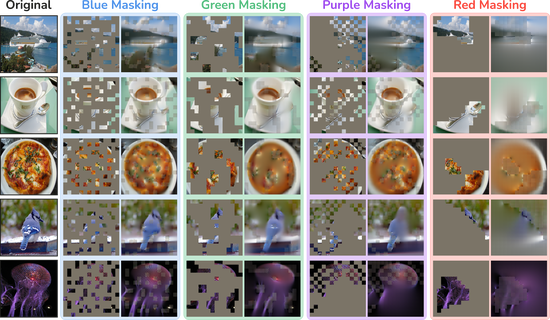
We explore data-independent masking strategies for Masked AutoEncoders (MAE), showing that carefully designed structured noise masks can match or improve upon learned/data-dependent masking, while being simpler and more efficient. See our Project Page!

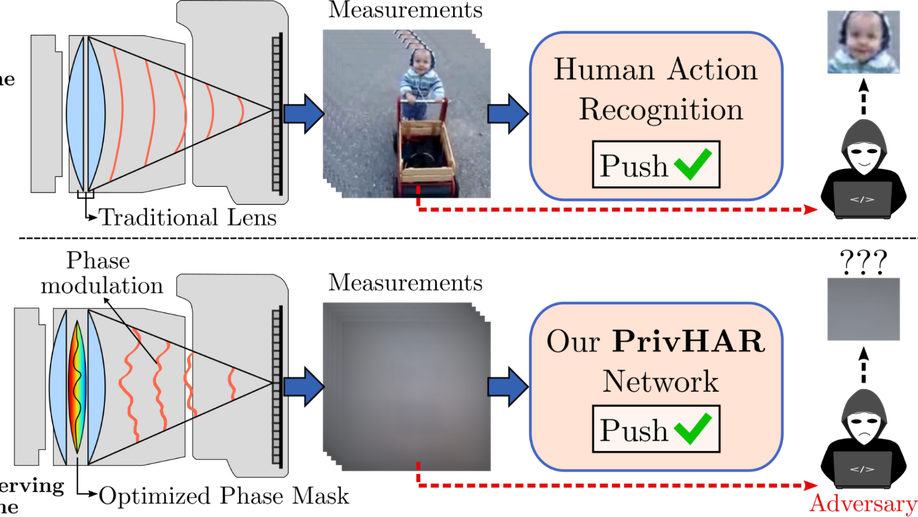
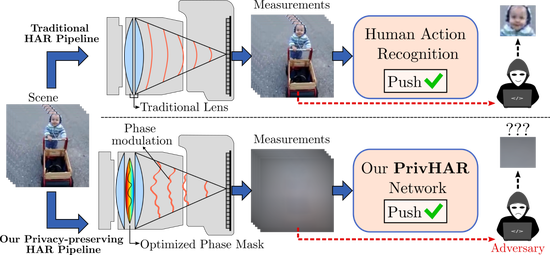
The accelerated use of digital cameras prompts an increasing concern about privacy and security, particularly in applications such as action recognition. In this paper, we propose an optimizing framework to provide robust visual privacy protection along the human action recognition pipeline. Our framework parameterizes the camera lens to successfully degrade the quality of the videos to inhibit privacy attributes and protect against adversarial attacks while maintaining relevant features for activity recognition. We validate our approach with extensive simulations and hardware experiments. See our Project Page!

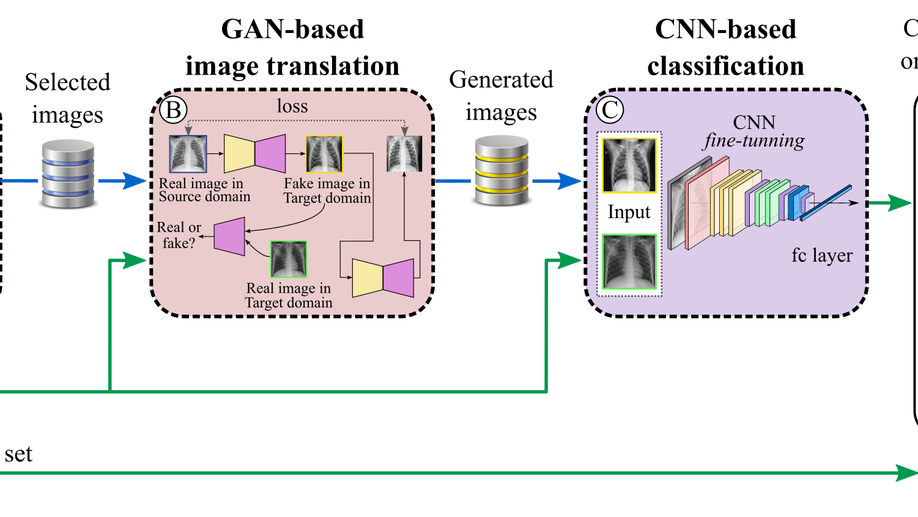
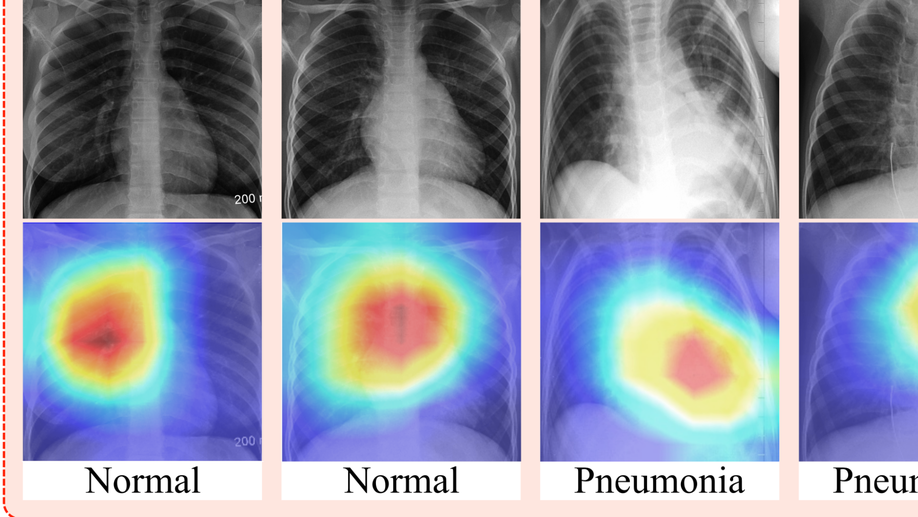
Recent advances in deep learning led to several algorithms for the accurate diagnosis of pneumonia from chest X-rays. However, these models require large training medical datasets, which are sparse, isolated, and generally private. Furthermore, these models in medical imaging are known to over-fit to a particular data domain source, i.e., these algorithms do not conserve the same accuracy when tested on a dataset from another medical center, mainly due to image distribution discrepancies. In this work, a domain adaptation and classification technique is proposed to overcome the over-fit challenges on a small dataset. This method uses a private-small dataset (target domain), a public-large labeled dataset from another medical center (source domain), and consists of three steps. First, it performs a data selection of the source domain’s most representative images based on similarity constraints through principal component analysis subspaces. Second, the selected samples from the source domain are fit to the target distribution through an image to image translation based on a cycle-generative adversarial network. Finally, the target train dataset and the adapted images from the source dataset are used within a convolutional neural network to explore different settings to adjust the layers and perform the classification of the target test dataset. It is shown that fine-tuning a few specific layers together with the selected-adapted images increases the sorting accuracy while reducing the trainable parameters. The proposed approach achieved a notable increase in the target dataset’s overall classification accuracy, reaching up to 97.78% compared to 90.03% by standard transfer learning.

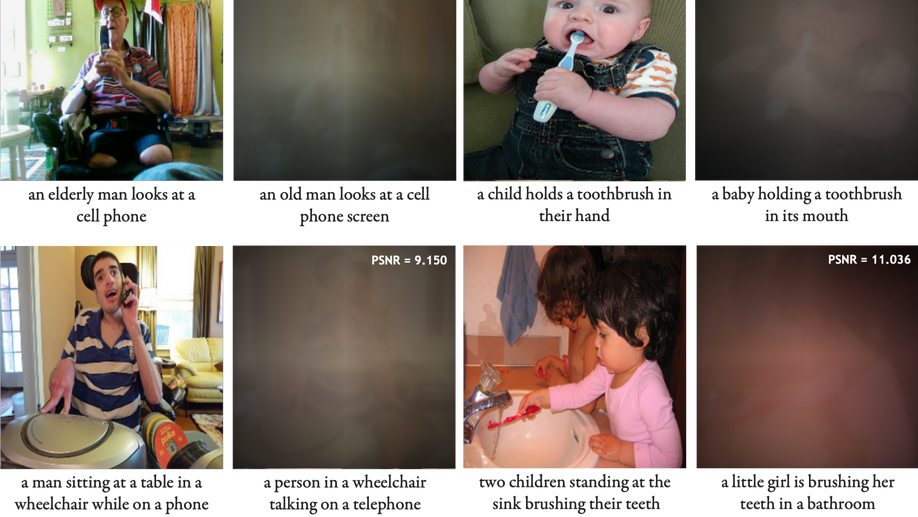
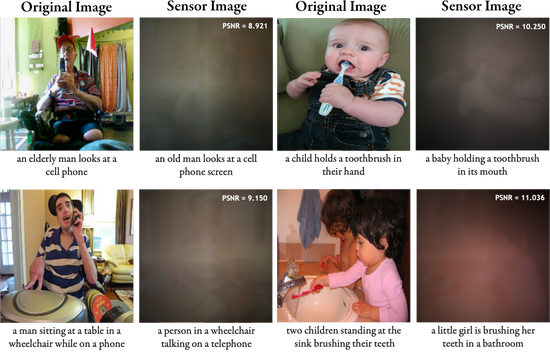
Image captioning is a challenging task that connects two major artificial intelligence fields: computer vision and natural language processing. Image captioning models use traditional images to generate a natural language description of the scene. However, the scene could contain private information that we want to hide but still generate the captions. Inspired by the trend of jointly designing optics and algorithms, this paper addresses the problem of privacy-preserving scene captioning. Our approach promotes privacy preservation, by hiding the faces in the images, during the acquisition process with a designed refractive camera lens while extracting useful features to perform image captioning. The refractive lens and an image captioning deep network architecture are optimized end-to-end to generate descriptions directly from the blurred images. Simulations show that our privacy-preserving approach degrades private visual attributes (e.g., face detection fails with our distorted images) while achieving comparable captioning performance with traditional non-private methods on the COCO dataset. See our Project Page!

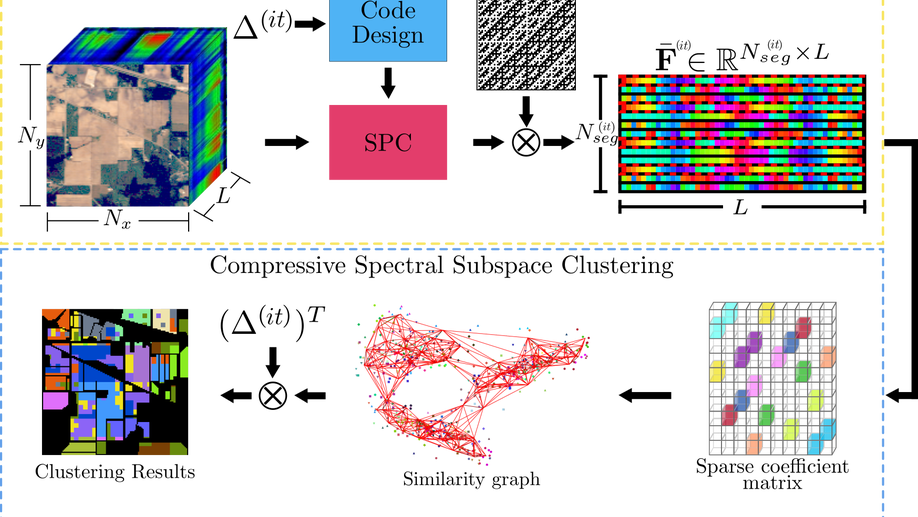
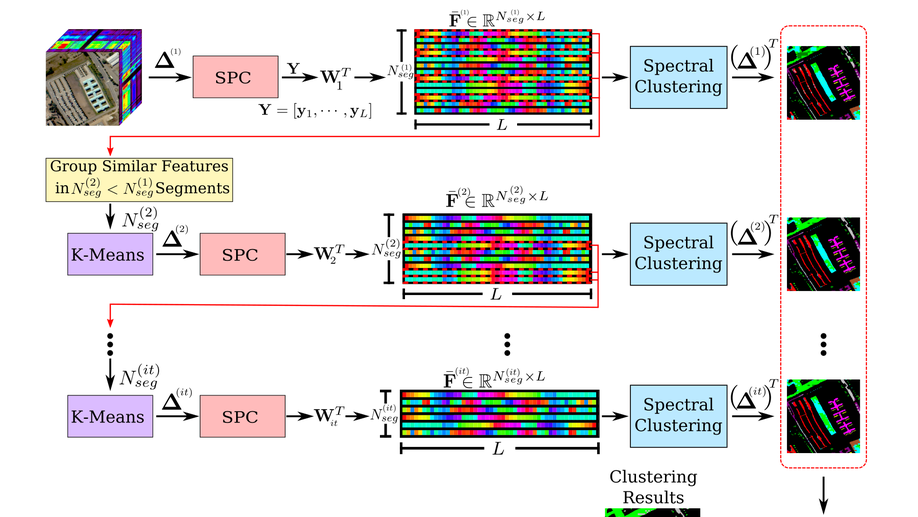
This paper proposes a hierarchical approach to design the sensing matrix of the SPC, such that the pixel clustering task can be performed directly using the compressed infrared SPC measurements without a previous reconstruction step. Specifically, a sensing matrix is designed to extract features directly from the compressed measurements at each hierarchy step. Then, a final segmentation map is obtained through majority voting in the partial clustering results.

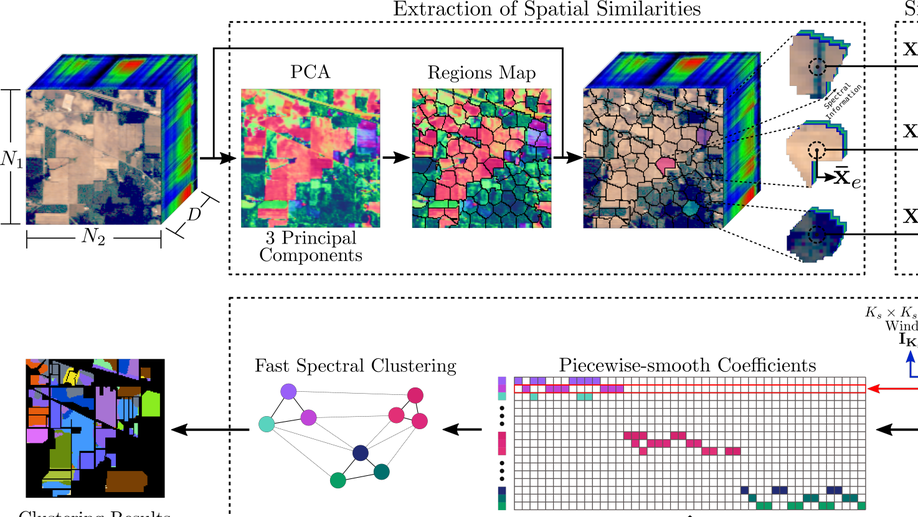
In this paper, we propose a fast algorithm that obtains a sparse representation coefficient matrix by first selecting a small set of pixels that best represent their neighborhood. Then, it performs spatial filtering to enforce the connectivity of neighboring pixels and uses fast spectral clustering to get the final clustering map.

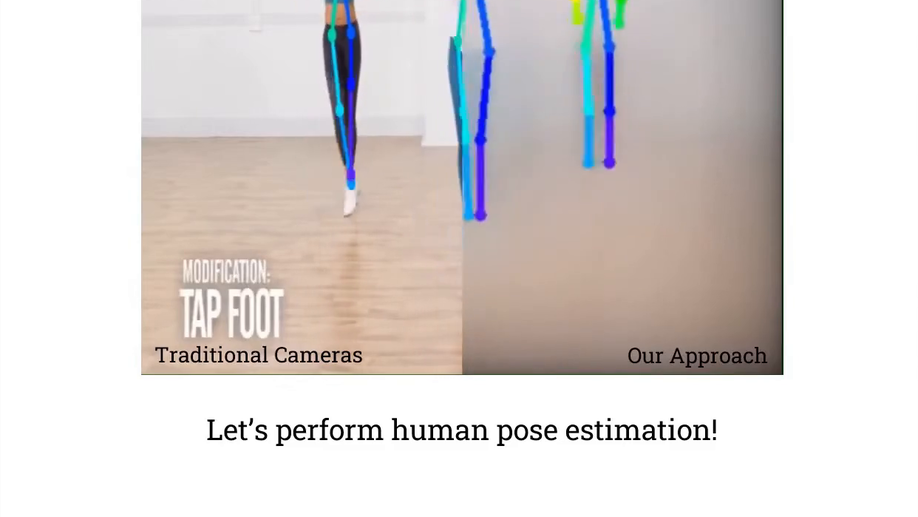
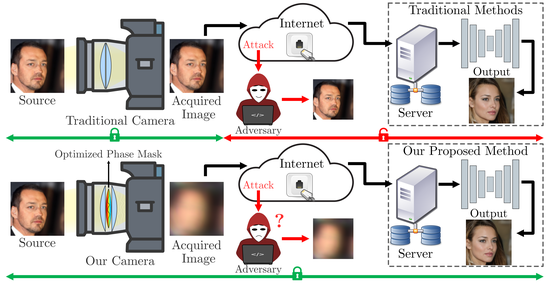
The widespread use of always-connected digital cameras in our everyday life has led to increasing concerns about the users privacy and security. How to develop privacy-preserving computer vision systems? In particular, we want to prevent the camera from obtaining detailed visual data that may contain private information. However, we also want the camera to capture useful information to perform computer vision tasks. Inspired by the trend of jointly designing optics and algorithms, we tackle the problem of privacy-preserving human pose estimation by optimizing an optical encoder (hardware-level protection) with a software decoder (convolutional neural network) in an end-to-end framework. We introduce a visual privacy protection layer in our optical encoder which, parametrized appropriately, enables the optimization of the point spread function (PSF) of the camera lens. We validate our approach with extensive simulations and a prototype camera. We show that our privacy-preserving deep optics approach successfully degrades or inhibits private attributes while maintaining important features to perform human pose estimation. See our Project Page!

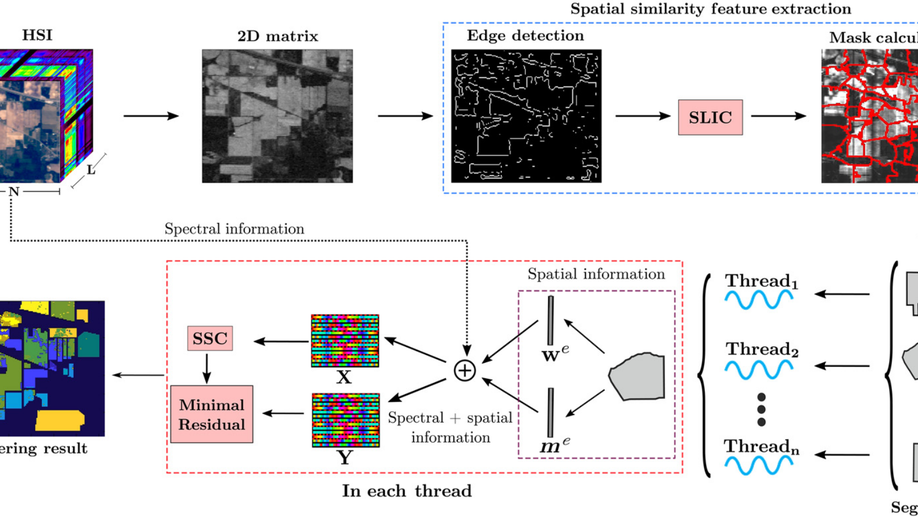
The unsupervised classification of hyperspectral images (HSIs) draws attention in the remote sensing community due to its inherent complexity and the lack of labeled data. Among unsupervised methods, sparse subspace clustering (SSC) achieves high clustering accuracy by constructing a sparse affinity matrix. However, SSC has limitations when clustering HSI images due to the number of spectral pixels. Specifically, the temporal complexity grows at a cubic ratio of the size of the data, making it inefficient for addressing HSI subspace clustering. We propose an efficient SSC-based method that significantly reduces the temporal and spatial computational complexity by splitting the HSI clustering task using similarity-constrained sampling. Our similarity-constrained sampling strategy considers both edge and superpixel information of the HSI to boost the clustering performance. This sampling strategy enables an intelligent selection of spectral signatures, and then, we split the clustering problem into multiples threads. Experimental results on widely used HSI datasets show that the efficiency of the proposed method outperforms baseline methods by up to 30% in overall accuracy and up to six times in computing time.

Recent advances in deep learning have led to an accurate diagnosis of pneumonia from chest X-ray images. However, these models usually require large labeled training datasets, not always available in practice. Furthermore, combining images from different medical centers does not preserve the accuracy of the results mainly because of differences in image acquisition settings. In this work, we propose an approach aiming to overcome this challenge, consisting of a subspace-based domain adaptation technique to increase pneumonia detection accuracy using a small training dataset. This dataset is augmented with automatically selected images from a large dataset acquired in a different medical center. This is performed by computing a subspace basis of the target domain dataset on which is projected the source dataset to find the most representative images. Augmenting the training set using the proposed method allows achieving an improvement from 90.03% to 96.18% in overall accuracy using the Xception neural network.

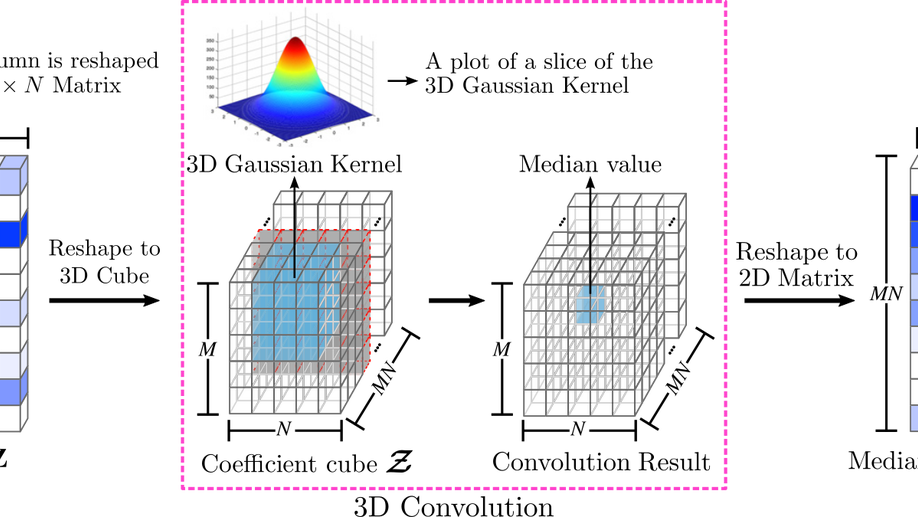
The accurate segmentation of remotely sensed hyperspectral images has widespread attention in the Earth observation and remote sensing communities. In the past decade, most of the efforts focus on the development of different supervised methods for hyperspectral image classification. Recently, the computer vision community is developing unsupervised methods that can adapt to new conditions without leveraging expensive supervision. In general, among unsupervised classification methods, sparse subspace clustering (SSC) is a popular tool that achieves good clustering results on experiments with real data. However, for the specific case of hyperspectral clustering, the SSC model does not take into account the spatial information of such images, which limits its discrimination capability and hampering the spatial homogeneity of the clustering results. As a solution, we propose to incorporate a regularization term to the SSC model, which takes into account the neighboring spatial information of spectral pixels in the scene. Specifically, the proposed method uses a three-dimensionall (3D) Gaussian filter to perform a 3D convolution on the sparse coefficients, obtaining a piecewise-smooth representation matrix that enforces an averaging constraint in the SSC optimization program. Extensive simulations demonstrate the effectiveness of the proposed method, achieving an overall accuracy of up to 99% in the selected hyperspectral remote sensing datasets.

In this work, we propose a hierarchical adaptive approach to design a sensing matrix of the single-pixel camera, such that pixel clustering can be performed directly on the compressed domain. We obtain overall accuracies of 79%, and 65%.

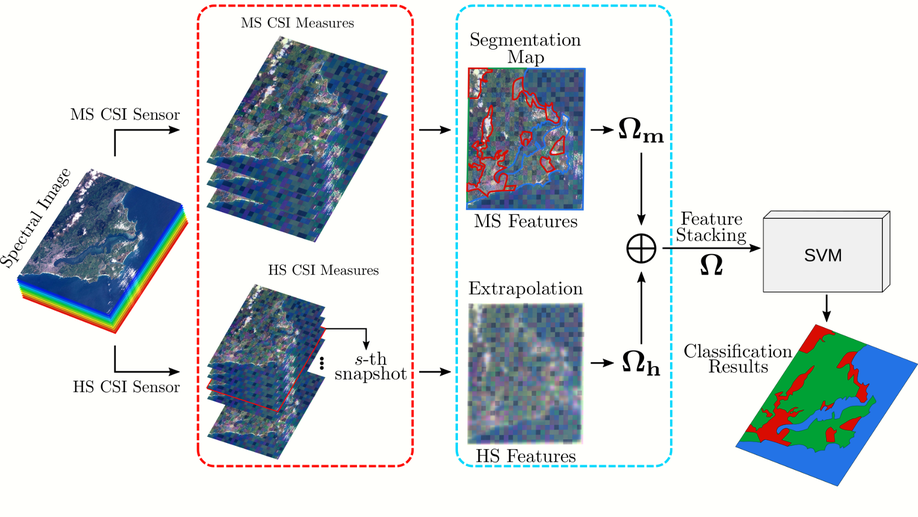
In this work, we propose to obtain features by considering the spectral information extracted from Hyperspectral CSI measurements, and the local spatial information extracted by clustering the Multispectral CSI measurements.

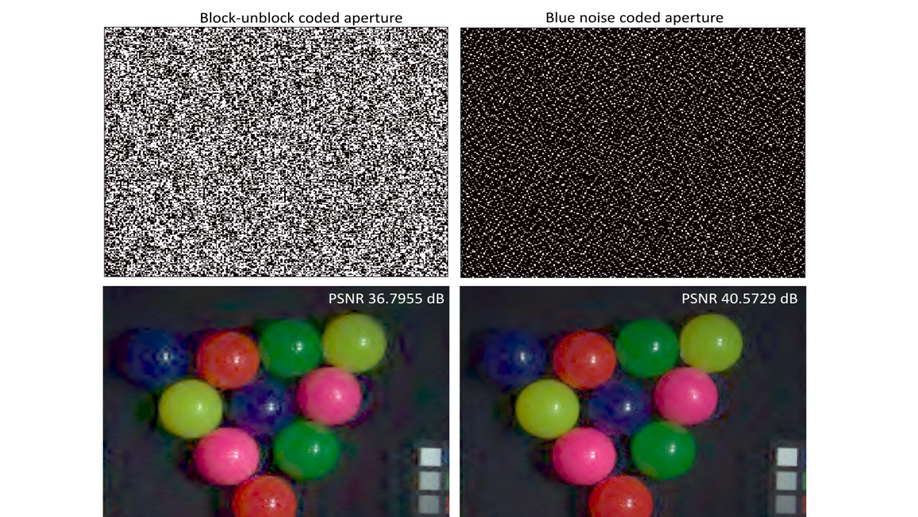
This paper proposes an adaptive grayscale coded aperture design which combines the advantages of blue noise and block-unblock coding patterns to provide high-quality image reconstructions and redundancy in the sampling.

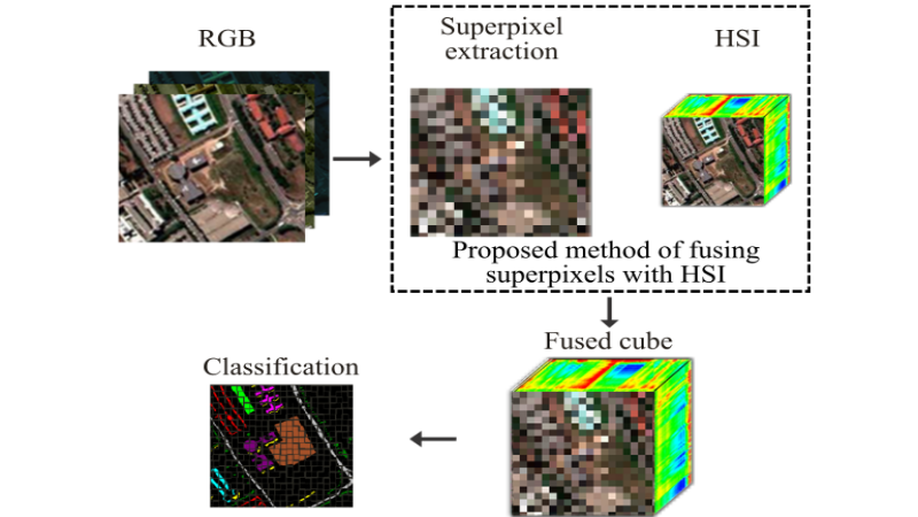
The proposed approach exploits the spatial information of an RGB image by grouping pixels with similar characteristics into superpixels and fuses such features with the spectral information of an HS image.

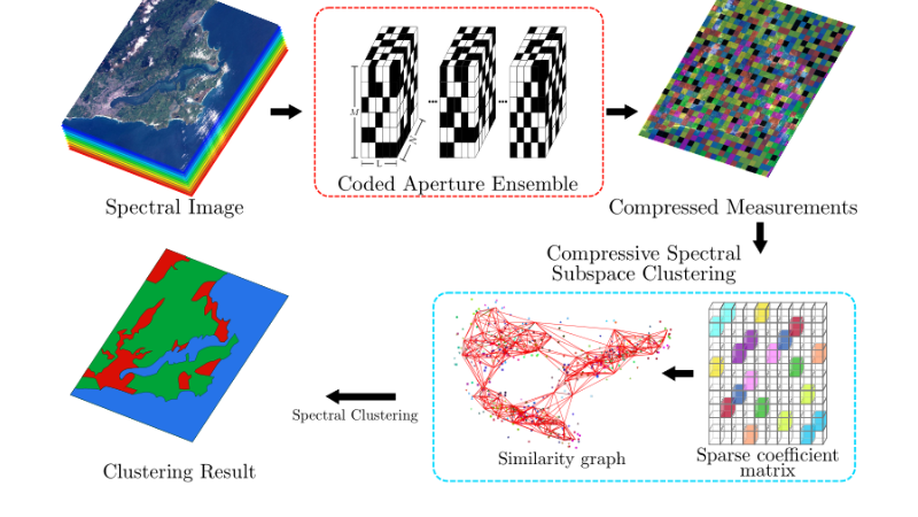
This paper proposes to design a set of coding patterns such that inter-class and intra-class data structure is preserved after the CSI acquisition in order to improve clustering results directly on the compressed domain. To validate the coding pattern design, an algorithm based on sparse subspace clustering (SSC) is proposed to perform clustering on the compressed measurements.

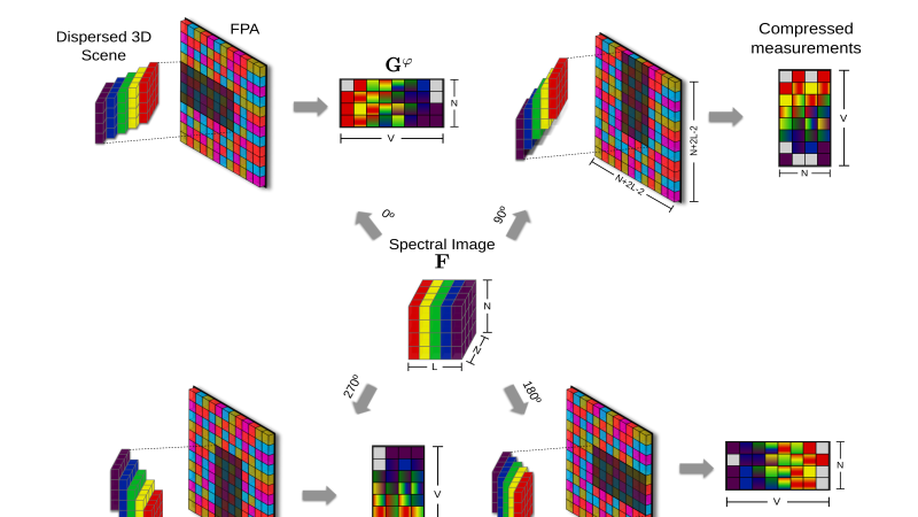
This paper extends the concept of SCCSI to a system admitting multiple snapshot acquisition by rotating the dispersive element, so the dispersed spatio-spectral source is coded and integrated at different detector pixels in each rotation. Thus, a different set of coded projections is captured using the same optical components of the original architecture.

Projects

*

Structured-Noise Masked Modeling for Video, Audio and Beyond

ECCV 2026 Oral. Structured masks built by filtering white noise into color noise for masked video and audio modeling, at no additional computational cost.

ColorMAE: Data-independent Masking for Masked AutoEncoders

ECCV 2024. Mask patterns generated by filtering random noise, which improve MAE representations without extra parameters or computation.

Privacy-preserving Optics for Enhancing Protection in Face De-identification

CVPR 2024. Privacy-preserving optics that strengthen protection in face de-identification.

Optics Lens Design for Privacy-preserving Scene Captioning

ICIP 2022 Best Paper Award. A designed optical lens that describes scenes while protecting the privacy of people in them.

PrivHAR: Recognizing Human Actions from Privacy-preserving Lens

ECCV 2022 Oral. An optical lens and adversarial training framework that recognize human actions while protecting privacy.

Learning Privacy-preserving Optics for Human Pose Estimation

In this project, we design the camera lens to perform human pose estimation while preserving users’ privacy.